Restrict origin 80/443 to CDN and verified bots with atomic sets
If a website is behind a CDN, only the CDN and verified bots should be able to reach the origin on 80/443; the rest are scanners. But everyone's IP lists can change daily, so I need a script that updates them without risking a firewall that fails to load or sits empty for even a fraction of a second.
1-minute summary
- Symptom / problem
- A web origin behind a CDN should accept only the CDN and verified search bots, but their IP lists change daily.
- Who should read
- Admins of VPS web servers that sit behind a CDN.
- Fix in short
- Restrict 80/443 to interval nft sets updated daily in one transaction, validate the data sources before touching the firewall, and keep a last-known-good copy.
I happened to check the nginx logs on a web VPS I had set up for a client and found hundreds of requests a day from unfamiliar addresses hitting the origin IP directly. Looking through the paths, they were probing for files that should not exist, even though all the site's DNS records were already proxied through the CDN. Real visitors could not have come from those addresses. I decided the origin should accept 80/443 only from the CDN's IP ranges, then wrote a script to fetch and update those ranges automatically every day. It sounded simple, but implementing it exposed two traps I had overlooked: search bots that bypass the CDN, and the interval when a set is empty during an update. This article covers the whole process using example set names and IP ranges, not the real ones.
Every table name, set name, and IP range in this article is an example I wrote for it, not an actual rule from any machine. Before using them, test on a machine with an alternative way in (the provider's console or a machine reachable over the internal network), because one incorrect rule can take the website down while the server itself is perfectly healthy.
Why the origin should accept no one except the CDN
The principle is simple. When DNS points to the CDN in proxied mode, every visitor talks to the CDN first, and the CDN then opens a new connection to the origin. That means connections reaching the actual nginx server should come only from the CDN's IP ranges. Anyone hitting the origin IP directly has already bypassed the CDN: scanners, bots probing randomly for vulnerabilities, or someone who found the origin in old DNS records.
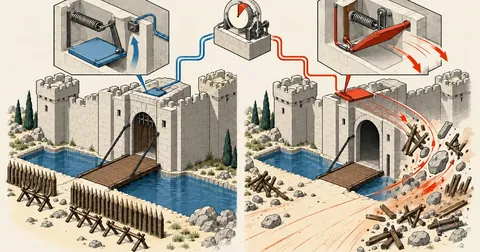
Anyone can reach 80/443
The CDN can filter only requests that pass through it. Requests sent directly to the IP all reach nginx, with no CDN WAF or rate limit in the way. The logs fill with junk, and nginx has to spend resources answering every one.
Only the CDN and verified bots
The web ports are open only to officially published IP ranges. Everything else is dropped at the firewall. nginx never even sees the connection attempts, and the logs are noticeably cleaner.
I consider this one of the cheapest layers of protection for a website behind a CDN, because I do not need to know about anyone's vulnerabilities. I just exclude traffic that should not be there in the first place. Anyone who wants to add another layer of rules is welcome to, but I think this layer should be in place.
The first trap: search bots that bypass the CDN
I followed the principle above literally and allowed only the CDN's ranges. A few days later, Search Console reported that it could not fetch the sitemap. At first, I suspected the sitemap file itself, but checking it showed nothing wrong. Next, I wondered whether a CDN rule was blocking bots, but that was not it either. I spent two or three hours on this before remembering that some search bots do not pass through the CDN. They fetch from their own addresses and connect directly to the origin through the domain name. I had just cut off that direct route myself.
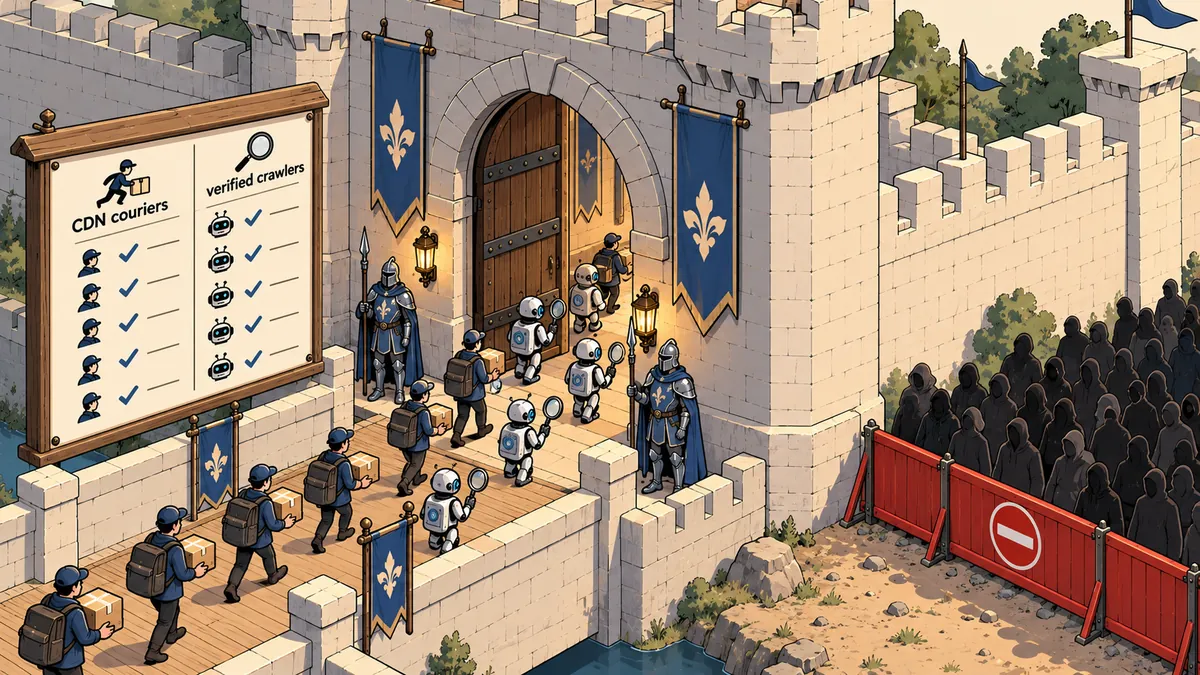
The conclusion was that the origin's allow list needs two groups. The first is the CDN's IP ranges. The second is bots whose providers publish an official IP list in a downloadable file. I gathered 12 sources in total: two CDN lists (v4 and v6 in plain text), bots from the major search engines including special fetchers triggered by users, bots from AI platforms that publish lists, and bots from one or two SEO tools. For bots without an official list, I do not guess their IP ranges. I let them connect only through the CDN.
Bots that do not publish IP ranges (including some that generate social link previews) cannot connect directly to the origin. They must go through the CDN, which they normally can do because they connect to the domain name pointing to it. On the other hand, if DNS is proxied and I forget to allow the CDN's ranges at the firewall, users will see the website go down while the server is healthy. Check both points after every change.
IP lists change, so the update needs to run daily
I do not expect providers' IP lists to stay the same forever. New ranges get added, and old ones get retired. If I hardcode the IPs in the firewall file once and forget about them, one day a range the CDN has just started using will be missing, causing intermittent outages that are hard to diagnose. I made a single Python script handle everything and set up a systemd timer to run daily at 03:40, with a random delay of up to 30 minutes so every machine in the world does not hit the same source at exactly the same time.
# web-allow.timer (ตัวอย่าง)
[Unit]
Description=Refresh web allow sets daily

[Timer]
OnCalendar=*-*-* 03:40:00
RandomizedDelaySec=30min
Persistent=true
OnBootSec=2min

[Install]
WantedBy=timers.target
Persistent=true means that if the machine is off at the scheduled time, it catches up when it comes back on. OnBootSec=2min runs it again after boot in case the set loaded from the old file is already out of date. The last log line of every run summarizes the counts by source. I can check that one line to see whether things look normal today. One run I checked had around a thousand v4 ranges and two hundred v6 ranges.
Validate sources before touching the firewall
My biggest concern is a source failing or returning something unexpected, and the script feeding it straight into the firewall. Imagine a response that is an error page or an empty file. The result could be an empty set and a complete website outage, or worse, an excessively broad range slipping through, such as /0, which opens access to the entire world. I always validate each source first.
- Fetch with a timeout of 30 seconds and read no more than 2,000,000 bytes. Treat anything larger as abnormal.
- Use a regex to extract only things that look like prefixes, without trusting the structure of the entire file.
- Pass every prefix to
ipaddress.ip_network. An invalid address raises ValueError. - Reject every non-global address, such as 10.x or 127.x, which often turn up in corrupt files.
- Reject ranges broader than the source's limit: for example, CDN prefixes no shorter than /12 for v4 and /29 for v6, and bot prefixes no shorter than /16 and /32.
- Reject empty lists or lists with more than 5,000 prefixes.
- Save sources that pass every check as the last known good copy. For sources that fail, use that copy instead.
import ipaddress, re, urllib.request

UA = "web-allow-updater/1.0"      # ชื่อกลาง ๆ ไม่ใส่โดเมน
MAX_BYTES = 2_000_000
MAX_PREFIXES = 5000
CIDR = re.compile(r'(?<![\w:.])([0-9a-fA-F:.]{2,45}/\d{1,3})(?!\w)')

def fetch(url):
    req = urllib.request.Request(url, headers={"User-Agent": UA})
    with urllib.request.urlopen(req, timeout=30) as r:
        raw = r.read(MAX_BYTES + 1)
    if len(raw) > MAX_BYTES:
        raise ValueError("response too large")
    return raw.decode("utf-8", "replace")

def validate(text, min_v4, min_v6):
    nets = []
    for c in CIDR.findall(text):
        n = ipaddress.ip_network(c, strict=False)   # ValueError ถ้าไม่ใช่ที่อยู่
        if not n.is_global:
            raise ValueError(f"non-global: {n}")
        floor = min_v4 if n.version == 4 else min_v6
        if n.prefixlen < floor:
            raise ValueError(f"too broad: {n}")
        nets.append(n)
    if not nets or len(nets) > MAX_PREFIXES:
        raise ValueError(f"unexpected count: {len(nets)}")
    return nets
If a required source—the CDN—has no data at all, with neither a successful live fetch nor an old copy available, the script logs nothing changed and exits with exit 1, without touching the firewall at all. I consider "I do not know" better than "I will guess" here. For failed bot sources, an old copy can serve for now because bot ranges do not change as often.
The update order must not change
This is the heart of the process. Initially, I thought writing a new file and running nft -f would be enough. There are actually two traps here. First, if even one include file referenced by nftables.conf is broken, nftables will fail to load on the next boot, leaving the machine running with no firewall at all. Second, if I flush the set and then add its members in a separate command, there is a brief interval between the two commands when the set is empty. Real CDN requests arriving at that moment get dropped.
The solution is that nft accepts multiple command lines from stdin as a single transaction. Every line succeeds together, or nothing changes at all.
The set structure and rules look roughly like this (abbreviated, with the machine's other rules omitted).
table inet fw {
    set web4 { type ipv4_addr; flags interval; auto-merge; }
    set web6 { type ipv6_addr; flags interval; auto-merge; }

    chain input {
        type filter hook input priority 0; policy drop;
        ct state established,related accept
        ip  saddr @web4 tcp dport { 80, 443 } accept
        ip  saddr @web4 udp dport 443 accept
        ip6 saddr @web6 tcp dport { 80, 443 } accept
        ip6 saddr @web6 udp dport 443 accept
    }
}
include "/etc/web-allow/web-allow.nft"
The udp 443 line lets QUIC through. Without it, browsers attempting HTTP/3 pause briefly before falling back to TCP. The interval type and auto-merge allow CIDR ranges to be added directly, and nft merges overlapping ranges automatically.
The script does three things in order. I put them in a single function to make it easy to follow.
import os, subprocess

def apply(v4, v6, final="/etc/web-allow/web-allow.nft"):
    new = final + ".new"
    body = []
    if v4: body.append("add element inet fw web4 { " + ", ".join(map(str, v4)) + " }")
    if v6: body.append("add element inet fw web6 { " + ", ".join(map(str, v6)) + " }")

    # 1) เขียนไฟล์ถาวรเป็น .new แล้วตรวจก่อน (include เสียหนึ่งไฟล์ = บูตมาไม่มีไฟร์วอลล์)
    with open(new, "w") as f:
        f.write("\n".join(body) + "\n")
    subprocess.run(["nft", "-c", "-f", new], check=True)

    # 2) อัปเดต set สดใน transaction เดียว ไม่มีช่วงที่ set ว่าง
    tx = "flush set inet fw web4\nflush set inet fw web6\n" + "\n".join(body) + "\n"
    subprocess.run(["nft", "-f", "-"], input=tx, text=True, check=True)

    # 3) ค่อยแทนไฟล์ถาวรเป็นขั้นสุดท้าย
    os.replace(new, final)
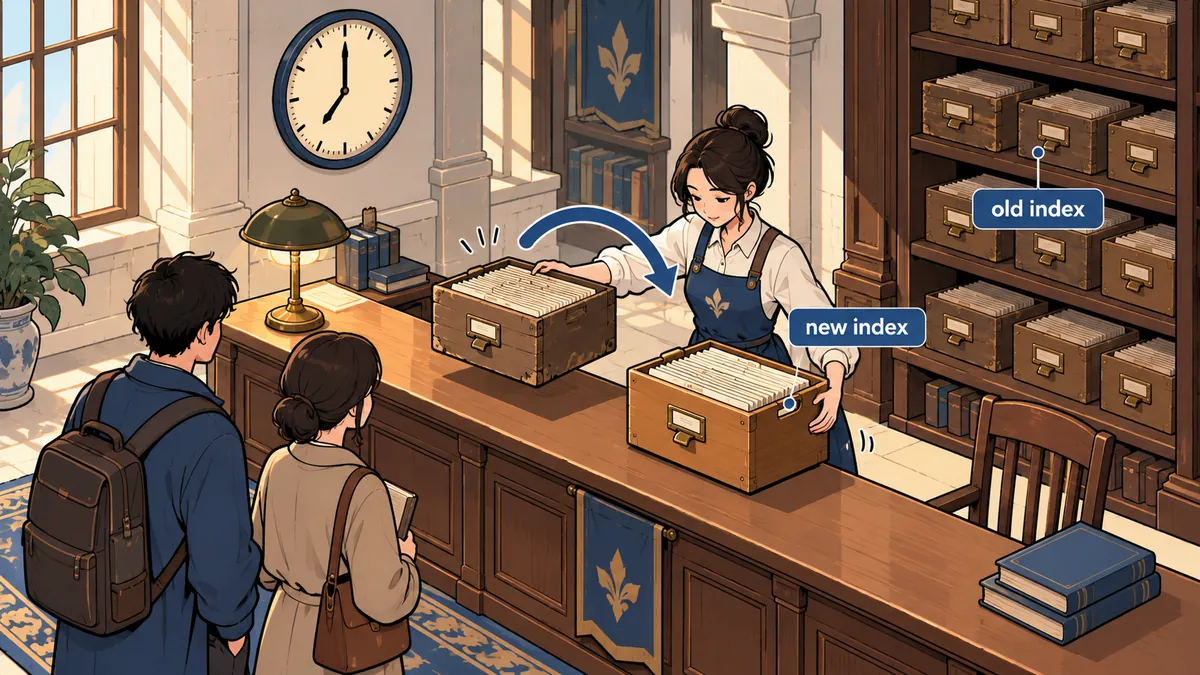
I ordered these steps from the least damaging failure to the most damaging. If nft -c fails, neither the actual file nor the live set changes. If the transaction fails, the live set stays as it was, and so does the persistent file. The final step is os.replace, a rename within the same filesystem, which is inherently atomic.
Regenerate nginx's real IP configuration in the same script
Once the origin accepts only the CDN, the next problem is that nginx sees the CDN's IP as the source of every request, making logs and rate limits unusable. It is the same issue I encountered in a form that failed to submit because of the IP behind a proxy. The solution is to tell nginx which IP ranges it can trust headers from. Those are the same CDN ranges I just fetched, so I have the same script regenerate nginx's file afterward.
# generated by web-allow-updater - do not edit by hand
set_real_ip_from 203.0.113.0/24;      # ตัวอย่าง ช่วงจริงถูกเติมโดยสคริปต์
set_real_ip_from 198.51.100.0/24;
real_ip_header   X-Client-IP;         # ชื่อ header ตามที่ CDN ของคุณส่งมา
The script writes this file, then runs nginx -t. If it passes, it reloads nginx. If it fails, it restores the original file so nginx will not encounter a broken config on the next reload. These two parts are linked because the addresses the firewall trusts as the CDN and those nginx trusts as the CDN should always be the same set. If the two differ, someone outside the CDN might be able to spoof headers.
Why not add and remove ranges individually?
Initially, I considered a smarter approach: compare the new list with the live set, then add only the new ranges and delete only the missing ones. The advantage is that unchanged parts of the set remain untouched. But when I tried implementing it, I found the complexity was not worth it. Because an interval set has auto-merge, a range I added might have merged with a neighboring range. The exact range I tried to delete would no longer exist in the set, causing the entire delete command to fail with an error. I spent about an hour on this before backing off.
Complex and error-prone
I have to reproduce nft's range merging myself. If my calculation differs from what nft actually merged, the whole delete batch fails, and intermediate states are hard to inspect.
Simple and predictable
On every run, the set exactly matches the list that just passed validation, with no accumulated state. If something goes wrong, the next run corrects it. The cost is sending roughly a thousand lines of ranges each time, which is tiny for the kernel.
I chose to flush the whole set in a single transaction because nft transactions already hide intermediate states from outside observers. A "flush" here therefore does not mean incoming packets ever see an empty set. The one precaution is to never split these two commands into two processes. Use nft -f - once, with a single input.
Another mistake I once made was placing the persistent file at a path writable by ordinary users. The file included at boot is owned by root and runs with the highest privileges. I keep it in its own directory, writable only by root, rather than in /tmp.
Test before letting the timer run on its own
I do not let the timer run for the first time without having seen the results. I test three things on a machine that still has another way in.
# 1) รันด้วยมือ แล้วเทียบ set สดกับไฟล์
python3 /usr/local/sbin/web-allow-update.py
nft list set inet fw web4 | head -n 20
nft list set inet fw web6 | head -n 20

# 2) ยัดไฟล์เสียแล้วดูว่า nft -c ปฏิเสธโดยไม่แตะของจริง
printf 'add element inet fw web4 { not-an-address }\n' > /tmp/bad.nft
nft -c -f /tmp/bad.nft; echo "exit=$?"

# 3) ปิดเครือข่ายออกแหล่งหนึ่ง (ให้ดึงล้ม) แล้วดูล็อกว่าใช้สำเนาเดิม
journalctl -u web-allow.service -n 30 --no-pager
The second test matters most to me because it proves that syntax validation really happens before anything reaches the live configuration. For the third, I point one source at an address that does not respond, then check that the log says it used the last known good copy and that the source's prefix count is unchanged.
What I gained and what still needs care
After enabling this, unfamiliar requests almost disappeared from the nginx logs because they no longer reach nginx. The firewall simply drops them silently. I consider that the intended result, but there are three limitations to understand. First, this does not replace a WAF. Requests coming through the CDN can still be attacks. Second, I rely on the accuracy of the lists published by providers. If they publish incorrect data, I follow them into the same mistake. Validation catches only malformed or overly broad entries, not errors in the actual content. Third, if I use an external website monitoring tool, I need to add its IP ranges to the list myself, or it will report the website as "down" every time it checks.
One thing I have not implemented yet is an alert when a source's prefix count changes unusually sharply in a single run. For now, I can inspect that manually in the log's summary line. If I have left gaps in the explanation or parts of the code need stricter checks, I will come back and improve them later.
Want us to set this up?
Get help with server setup, configuration, migration, or troubleshooting. Save time for the work that matters.
Hit something like this? Stuck somewhere?
Come trade notes on the LinuxThai board
Comments 0
No comments yet — be the first