A Frozen UI and Silent Logs: A BUSY, BLOCKED, STARVED Watchdog
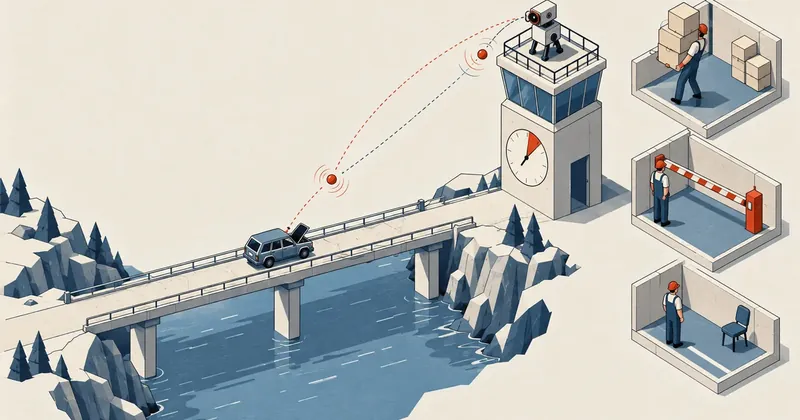
A silent log does not mean nothing happened. It only means the thread responsible for writing the log did not write anything. To find out why, I need another thread that does not freeze along with it, recording what the stalled thread is doing.
1-minute summary
- Symptom / problem
- A C# app froze for about 2 minutes while the backend kept running, and the log went silent with no way to prove the cause afterwards
- Who should read
- Developers of desktop apps whose UI freezes at times with nothing in the log
- Fix in short
- Add a watchdog thread that posts a sequence-number message to the UI queue every 250 ms and reports whether the UI thread is BUSY, BLOCKED or STARVED, with one dump.
A real-time data monitoring UI I wrote in C# froze for around 2 minutes, then its process disappeared, while the engine running as its child process kept working normally. I opened the UI log to see what had happened and found that it told me nothing at all. The last line was an ordinary stats line, followed by silence. I made three wrong guesses before accepting that I could not prove the cause of this incident from the available data. What I could do was build the tools to prove it next time.
In this article, I call the UI application the control panel and the backend process the engine. I have removed all real names, paths and data details. The timings, thread counts and sequence of events are real.
What the log says, and what it does not
These are all the facts I could get from the control panel log. I have shortened it to just the outline. Times are measured from the last stats line.
t+0 s     stats: frames +105 ใน 10 วินาที          # บรรทัดปกติบรรทัดสุดท้ายจาก UI thread
          (เงียบ)
t+50 s    thread เบื้องหลัง: poll สถานะ timeout     # ประมาณ 50 วินาทีต่อมา
          thread เบื้องหลัง: poll สถานะกลับมาตอบ
          (เงียบ)
          ไม่มีบรรทัด exit 0                       # process หายไปภายในสองนาที
Nothing was wrong on the engine side. Its round trip times stayed within the normal range for the day: 10-268 ms. This was not luck; it was a result of the design. The control panel only reads shared memory and writes to a command channel. There is no path where the engine has to wait for the control panel. The control panel dying therefore cannot push the problem back onto the engine.
What the log does not answer is the one question I wanted answered: what was the UI thread doing during that silence? Was it looping, waiting for something, or ready to run but getting no CPU time? Those three answers lead to fixes in completely different places, and the existing log could not distinguish between them.
Three wrong guesses worth recording
First guess: a bug in the rendering path Shortly before the freeze, the list on screen went from 1 row to 0 rows. I suspected something was wrong with rendering an empty list. Tracing the code ruled that out, and there was clear evidence against it. The same sequence had happened 5 minutes earlier on the same build, and the control panel had continued rendering normally.
Second guess: an infinite loop While tracing the code, I did find a hidden infinite loop. It was in a function that estimates text height, which would loop forever if the width passed to it was less than or equal to zero. It explained the freeze so neatly that I could almost have closed the case. But when I traced its callers, the production path did not use that code at all. It was a real bug worth fixing, but it was not the cause of this incident.
Third guess: the gap between frames lines proved a freeze This was a mistake in how I read the log. My stats lines were only emitted when a frame was presented. A minimised window presents no frames at all. Looking back through logs from other days, I found gaps of 760 seconds and 5,080 seconds on days with no problems at all. Missing lines therefore did not mean a freeze. All they could mean was that there were no frames.
The infinite loop I found along the way was a real bug, and it explained the freeze neatly. If I had stopped there, I would have fixed it, declared the job done, and waited for the same symptom to return. The question I need to ask every time is: was the buggy path actually called during this incident? If I cannot answer yes, it is still not the cause.
The leading suspect I could not prove
The only concurrent event that could explain the symptoms was a release build of the engine on the same machine. The build had started around 2 minutes earlier, with 14 compiler processes continuously using all 16 threads at 100%, followed by another build of the test suite.
To put it plainly, the cause could not be proven from the available logs. CPU starvation was the leading suspect, but it was only the leading suspect, not a conclusion. I had no data on how much CPU time the UI thread received during that period, and no stack for it. Writing "the build took CPU away" as the cause would turn a likelihood into a false fact. The remaining work therefore had two parts: make it possible to prove the cause next time, and reduce the chance of the leading suspect happening in the meantime.
An in-process watchdog: a numbered message every 250 ms
An external monitor like the one I previously wrote about in the article about a watchdog that counted itself can only tell whether the process is still there. In this incident, the answer was yes throughout the freeze. What I needed was a monitor inside the same process, able to see the same threads and tell what kind of stall it was.
The mechanism is simple. A thread other than the UI thread queues a numbered message to the window using PostMessage every 250 ms. The UI thread receives it and records the latest number received. If the UI thread is still running its message loop, the message will be received within a few milliseconds. If a message is not received within 3 seconds, I treat it as a stall.
I separated the timing logic into a class with no clock of its own. It takes the current time as a number. That lets me test it without waiting even a millisecond of real time.
public sealed class HangMonitor
{
    public long StallMs = 3000, DumpMs = 10_000, RepostMs = 2000, RepeatMs = 30_000;
    private long _sent, _acked, _sentAt, _postedAt, _reportedAt = -1, _stallFrom;
    private bool _dumped;

    public readonly struct Step
    {
        public bool Post { get; init; }        // ให้โพสต์ข้อความเลข Seq เข้าหน้าต่างตอนนี้
        public long Seq { get; init; }
        public bool Report { get; init; }      // ให้เขียนรายงาน UI STALL
        public bool Dump { get; init; }        // ให้สั่ง dump (ครั้งเดียวต่อการรัน)
        public long EndedMs { get; init; }     // การค้างเพิ่งจบ: ยาวกี่ ms (0 = ไม่มี)
        public long StalledMs { get; init; }
    }

    // UI thread เรียกเมื่อรับข้อความเลข seq แล้ว
    public void Ack(long seq)
    {
        long a;
        do { a = Interlocked.Read(ref _acked); }
        while (seq > a && Interlocked.CompareExchange(ref _acked, seq, a) != a);
    }

    // watchdog thread เรียกทุก 250 ms
    public Step Check(long now)
    {
        if (Interlocked.Read(ref _acked) >= _sent)
        {
            long ended = _reportedAt >= 0 ? Math.Max(1, now - _stallFrom) : 0;
            _reportedAt = -1;
            _sent++;
            _sentAt = _postedAt = now;
            return new Step { Post = true, Seq = _sent, EndedMs = ended };
        }
        long stalled = now - _sentAt;
        bool repost = now - _postedAt >= RepostMs;       // เผื่อข้อความที่โพสต์ไปหาย
        if (repost) _postedAt = now;
        bool report = false, dump = false;
        if (stalled >= StallMs && (_reportedAt < 0 || now - _reportedAt >= RepeatMs))
        {
            if (_reportedAt < 0) _stallFrom = _sentAt;
            _reportedAt = now;
            report = true;
        }
        if (stalled >= DumpMs && !_dumped) { _dumped = true; dump = true; }
        return new Step { Post = repost, Seq = _sent, Report = report, Dump = dump, StalledMs = stalled };
    }
}
On the UI thread, the only extra work is two lines in the window procedure: record which message is being handled, and acknowledge the watchdog message.
private const uint WM_APP = 0x8000;
private const uint WM_WATCHDOG = WM_APP + 41;

private IntPtr WndProc(IntPtr hwnd, uint msg, IntPtr wParam, IntPtr lParam)
{
    _watchdog.Seen(msg);                               // เขียนตัวแปรสองตัว ถูกพอจะเรียกทุกข้อความ
    if (msg == WM_WATCHDOG)
    {
        _watchdog.Ack(wParam.ToInt64());               // เลขลำดับมากับ wParam
        return IntPtr.Zero;
    }
    return HandleMessage(hwnd, msg, wParam, lParam);   // ข้อความอื่นของหน้าต่างตามปกติ
}
One detail that matters is setting the watchdog thread's priority to above normal. If the machine is so heavily loaded that the monitor itself cannot run, there is nobody left to record anything. During a stall, it does not post a new message every 250 ms. It only reposts the same number every 2 seconds. That keeps the watchdog from flooding the window's message queue.
Three classifications: BUSY, BLOCKED, STARVED
Once I know there is a stall, the next question is what kind. I use two measurements that I can read from outside the UI thread without its cooperation. The first is the CPU time the UI thread has used during the stall, read with GetThreadTimes through a handle opened once at startup. The second is the thread state from Process.Threads.
// _uiThread = OpenThread(THREAD_QUERY_LIMITED_INFORMATION, false, uiThreadId) เปิดครั้งเดียวตอนสตาร์ต
// _uiCpuAtPost = เวลา CPU ของ UI thread ตอนโพสต์ข้อความที่ยังไม่ถูกรับ
private string Verdict(long stalledMs)
{
    string state = "?";
    using (Process me = Process.GetCurrentProcess())
        foreach (ProcessThread t in me.Threads)
            if (t.Id == _uiTid)
                state = t.ThreadState == System.Diagnostics.ThreadState.Wait
                    ? "Wait/" + t.WaitReason                 // WaitReason อ่านได้เฉพาะตอนสถานะเป็น Wait
                    : t.ThreadState.ToString();

    if (!GetThreadTimes(_uiThread, out _, out _, out long kernel, out long user))
        return "UNKNOWN, state " + state;
    double usedMs = (TimeSpan.FromTicks(kernel + user) - _uiCpuAtPost).TotalMilliseconds;

    if (usedMs > 0.6 * stalledMs) return $"BUSY, cpu {usedMs:0} ms, state {state}";
    if (state.StartsWith("Wait", StringComparison.Ordinal)) return $"BLOCKED, state {state}";
    return $"STARVED, cpu {usedMs:0} ms, state {state}";
}

[DllImport("kernel32.dll")]
private static extern bool GetThreadTimes(IntPtr h, out long create, out long exit, out long kernel, out long user);
| Verdict | Condition | Meaning | Where to look next |
|---|---|---|---|
| BUSY | UI thread CPU time exceeds 60% of the stall duration | A loop or heavy workload is running on the UI thread | Stack in the dump, latest phase in the report |
| BLOCKED | Thread state is Wait | Waiting for a lock, I/O or another thread | WaitReason, states of other threads in the app |
| STARVED | Everything else: low CPU use and not in the Wait state | Ready to run but getting no CPU time | Total machine CPU usage, the top 6 CPU-consuming processes |
A single report line therefore records more than the verdict. It includes the latest window message the UI thread is handling, the latest phase (frame build, frame render or wake refresh), UI thread CPU time during the stall, total machine CPU usage, the 6 processes consuming the most CPU, and the states of every thread in the app.
# รูปแบบของบรรทัดรายงาน (ค่าในวงเล็บแหลมคือค่าที่วัดได้ตอนนั้น)
UI STALL <n> s: the UI thread (tid <id>) has not taken the watchdog message;
  last window message <msg> <n> s ago; phase '<frame build|frame render|wake refresh>' since <n> s;
  UI thread state <state>, cpu <n> ms during the stall -> <BUSY|BLOCKED|STARVED>;
  system cpu <n>% of 16 threads; top processes <name xN pct>, ...; threads <id state cpu>, ...
UI STALL ended after <n> s
The thread state is a snapshot at one instant, and STARVED is defined by elimination: neither BUSY nor Wait. That makes it the least certain of the three classifications. This is why I have the report print every raw measurement as well. If the verdict says STARVED and total machine CPU usage is at 100%, with a list of the processes consuming it, that is credible. If it says STARVED while the machine is idle, I need to open the dump and inspect it myself.
One dump, and a heartbeat independent of frames
A single report line can tell what kind of stall it is, but for BUSY or BLOCKED, what I really want is a stack. After a stall exceeds 10 seconds, the watchdog therefore invokes createdump, which already comes with the .NET runtime, to dump its own process with the heap once per run. It retains only the latest 3 files, because dumps that include the heap are large. If I let it dump on every stall, the disk would fill up before anyone came to read them.
private void Dump()
{
    string exe = Path.Combine(RuntimeEnvironment.GetRuntimeDirectory(), "createdump.exe");
    if (!File.Exists(exe)) { _log.Warn("UI STALL dump: ไม่พบ createdump ข้าง runtime"); return; }

    Directory.CreateDirectory(_dumpDir);
    FileInfo[] olds = new DirectoryInfo(_dumpDir).GetFiles("ui-*.dmp");
    Array.Sort(olds, (a, b) => b.LastWriteTimeUtc.CompareTo(a.LastWriteTimeUtc));
    for (int i = 2; i < olds.Length; i++)                      // เหลือ 2 ไฟล์เก่า + ไฟล์ใหม่ = 3
        try { olds[i].Delete(); } catch (IOException) { }

    string file = Path.Combine(_dumpDir, $"ui-{Environment.ProcessId}-{DateTime.UtcNow:yyyyMMdd-HHmmss}.dmp");
    var si = new ProcessStartInfo(exe) { UseShellExecute = false, CreateNoWindow = true };
    si.ArgumentList.Add(Environment.ProcessId.ToString(CultureInfo.InvariantCulture));
    si.ArgumentList.Add("-f");
    si.ArgumentList.Add(file);
    si.ArgumentList.Add("--withheap");
    using Process? p = Process.Start(si);
    bool done = p != null && p.WaitForExit(60_000);
    _log.Warn(done && File.Exists(file) ? "UI STALL dump written: " + file : "UI STALL dump failed: " + file);
}
I can inspect it directly with the standard .NET tools.
dotnet tool install -g dotnet-dump
dotnet-dump analyze ui-<pid>-<เวลา>.dmp
> clrstack -all          # managed stack ของทุก thread รวม UI thread ที่ค้าง
> clrthreads             # รายการ managed thread และสถานะ
I also fixed the issue behind my third wrong guess. I moved the stats lines, previously emitted with frames, onto the watchdog's 250 ms tick. The log now has a heartbeat every 10 seconds even when no frames are drawn. If the window is minimised, that line says MINIMISED. The next gap in the log will have only one interpretation, without having to guess whether it is silent because of a stall or because there is nothing to draw.
Prevention: builds must run below the live system
Even if I could not prove the build was the cause, letting 14 compilers compete for CPU with a live system on the same machine was a risk I had no reason to accept. I addressed it in two ways.
- The control panel and engine set their priority class to ABOVE_NORMAL at startup. I do not use HIGH or REALTIME because, at those levels, a loop in my own program could take CPU away from operating system work and make the entire machine slow to respond.
- The build and deploy scripts lower their own priority to BELOW_NORMAL before invoking the compiler. On Windows, child processes created by a parent at BELOW_NORMAL or IDLE inherit that level by default. Every compiler therefore runs at the same level without having to set each one individually.
- I limit build parallelism so it does not consume every thread. The .NET side uses
-m:4, while the engine uses 6 jobs for builds and 4 threads for tests, on a 16-thread machine. - I always restore the script's original priority in
finally. Otherwise, steps after the build, such as restarting the system, would inherit the lower level too.
# ส่วน build ของสคริปต์ deploy
$me = Get-Process -Id $PID
$prio = $me.PriorityClass
$me.PriorityClass = 'BelowNormal'          # compiler ที่ถูกเรียกต่อจากนี้ได้ระดับเดียวกัน
try {
    cargo build --release -j 6
    if ($LASTEXITCODE -ne 0) { throw 'build เอนจินล้ม' }
    cargo test --release -j 6 -- --test-threads=4
    if ($LASTEXITCODE -ne 0) { throw 'เทสต์เอนจินล้ม' }
    dotnet publish .\ui\Ui.csproj -c Release -m:4
    if ($LASTEXITCODE -ne 0) { throw 'publish หน้าจอล้ม' }
}
finally { $me.PriorityClass = $prio }       # ขั้นตอนถัดไปต้องไม่ติดระดับต่ำไปด้วย
// บรรทัดแรก ๆ ของ Main ทั้งหน้าจอและเอนจิน (ฝั่งเอนจินใช้ API เทียบเท่าในภาษาของมัน)
using (Process me = Process.GetCurrentProcess())
    me.PriorityClass = ProcessPriorityClass.AboveNormal;
Testing the watchdog itself
A monitor whose intended execution paths have never been tested is a monitor I do not yet know works. Because HangMonitor has no clock of its own, the tests can feed time directly as numbers and finish in a fraction of a second.
[Fact]
public void ReportsAtThreeSeconds_ThenAgainAfterThirty_AndDumpsOnce()
{
    var m = new HangMonitor();
    Assert.True(m.Check(0).Post);                    // โพสต์ #1 แล้วไม่มีใคร ack เลย

    int reports = 0, dumps = 0;
    for (long now = 250; now <= 34_000; now += 250)
    {
        HangMonitor.Step s = m.Check(now);
        if (s.Report) reports++;
        if (s.Dump) dumps++;
    }
    Assert.Equal(2, reports);                        // ที่ 3 วินาที และที่ 33 วินาที
    Assert.Equal(1, dumps);                          // ที่ 10 วินาที ครั้งเดียว
}

[Fact]
public void LateAckEndsTheStallAndReportsItsLength()
{
    var m = new HangMonitor();
    HangMonitor.Step first = m.Check(0);
    for (long now = 250; now <= 5000; now += 250) m.Check(now);

    m.Ack(first.Seq);                                // UI thread กลับมารับข้อความ
    HangMonitor.Step after = m.Check(5250);
    Assert.Equal(5250, after.EndedMs);               // ค้างยาว 5,250 ms นับจากข้อความที่ไม่ถูกรับ
    Assert.True(after.Post);                         // แล้วเริ่มรอบใหม่ด้วยเลขถัดไป
}
The watchdog has 6 tests covering a single stall, repeated reports during a stall, one dump per run, a log line when a stall ends, late acknowledgements, and a final test using a real thread that never acknowledges anything, to verify the full cycle beyond the logic alone.
There was another finding from the same issue. Two existing timing tests had occasionally failed under heavy machine load, which was the same problem on a smaller scale. Tests that measure real elapsed time on a machine running a build say less about the code than they do about the machine.
Logging tied to the UI thread
- Stats emitted only when there are frames
- Silence = stalled or minimised; no way to tell
- Nobody records anything during a stall
- The cause has to be guessed after the fact
A separate watchdog thread
- A heartbeat every 10 seconds, showing MINIMISED
- A 3-second stall produces a report with a verdict
- A 10-second stall produces a dump with stacks
- The stall duration is known when it ends
I still cannot say what caused that incident, and I will not write that I can. What has changed is that the next time the UI stalls for more than 3 seconds, the log will contain a line showing how much CPU time the UI thread used, what state it was in, how heavily loaded the machine was, and which processes were consuming CPU. That is enough to distinguish the three cases. Personally, I think this kind of tool should be there from day one in an app with a single UI thread, because its cost is one thread waking every 250 ms and a few hundred lines of code. Anyone using it can adjust the 3-second and 60% thresholds to suit their workload. When the first report from a real incident arrives, I will come back and update this article.
Hit something like this? Stuck somewhere?
Come trade notes on the LinuxThai board
Comments 0
No comments yet — be the first