Upgrading 3 Proxmox Nodes: One Slowed Down by 509 Locales
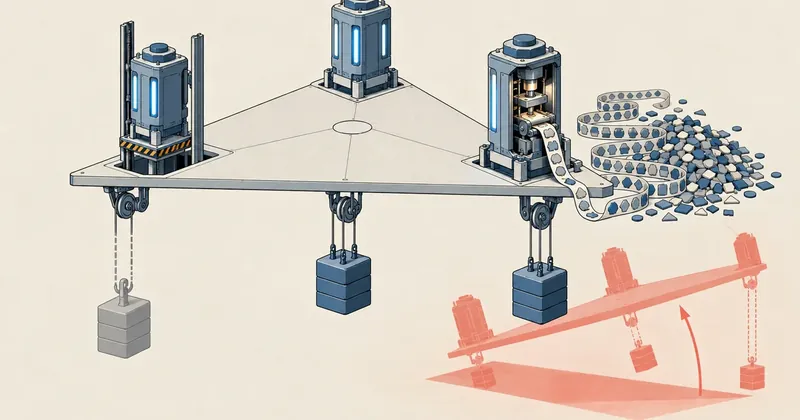
A three-node cluster can tolerate losing only one node at a time, and that rule still applies on a night when I am the one taking nodes down. A safe upgrade therefore depends less on the apt command than on the reboot order and knowing whether the slow node is making progress or stuck.
1-minute summary
- Symptom / problem
- Upgrading a 3-node Proxmox cluster at once, two nodes finish in about 5 minutes and one looks hung.
- Who should read
- Admins of a three-node Proxmox cluster running dist-upgrade.
- Fix in short
- The slow node is only compiling 509 locales, not hung. Reboot one node at a time so 2 of 3 always stay up.
An end user could not connect remotely to a VM on my 3-node Proxmox cluster. The owner decided that since I had to work on it anyway, I should update the whole cluster. The instruction was brief: stop all VMs and run apt update upgrade on all 3 machines. I launched the scripts on all three at 19:04. Two finished within five minutes. The third went quiet long enough for the owner to ask why it was slow when it was usually fast. Then came the more important question: could I reboot the two finished machines first?
In this article I call the three machines node A, B, and C, with B being the slow one. I am leaving out the software version numbers; this was an upgrade from the previous minor release to the latest minor release in the same series, for both the manager and the kernel. It was not a major version upgrade like the one described in Using Claude to Upgrade Proxmox 8 to 9 and Rebuild Windows VMs Across the Cluster. The times, package counts, and measurements are real.
Before the upgrade: RAM at 100.70% was not the problem
Before getting to the upgrade, there was one wrong guess worth covering. One VM's summary page showed RAM at 100.70%. It looked as though the VM had run out of memory and could no longer accept remote connections. But this figure did not come from inside the guest. That VM had ballooning disabled (balloon: 0), and the guest agent was not running, so Proxmox had no memory usage figures from inside it. What it displayed instead was the RSS of the kvm process on the host, which includes device emulation overhead. That can exceed 100% of the memory allocated to the VM.
The host confirmed there was no memory pressure at all.
free -g | sed -n 2p            # Mem: รวม 32 GB ใช้ 16.8 GB available 15.1 GB
cat /proc/pressure/memory
# some avg10=0.00 avg60=0.00 avg300=0.00 total=...
# full avg10=0.00 avg60=0.00 avg300=0.00 total=...
dmesg -T | grep -ci 'out of memory'    # 0
uptime                                  # load average 0.44
The percentage on the summary page of a VM with ballooning disabled and no guest agent is the size of the kvm process, not usage inside the guest. What tells you whether the machine is actually short of memory is /proc/pressure/memory. If every value is 0.00 and there is no OOM in the log, nothing is waiting for memory.
The actual cause of the failed remote connection was much more mundane. The user was connecting to the wrong IP, an address that no machine on the network held. It had nothing to do with memory or the Proxmox version. But by then the owner had already decided to update, so the work continued.
The upgrade script on each node: check, stop guests, then dist-upgrade
Each node ran the same script detached, wrote its log to a file, and finished with a marker file containing a one-word result. The reason for detaching it was that if SSH disconnected halfway through, dpkg must not die with it.
#!/bin/bash
# /root/pve-upgrade.sh -- เรียกด้วย: nohup /root/pve-upgrade.sh >/dev/null 2>&1 &
LOG=/root/pve-upgrade.log
MARK=/root/pve-upgrade.marker
exec >>"$LOG" 2>&1
rm -f "$MARK"
fail() { echo "DONE-FAIL $*" | tee "$MARK"; exit 1; }

# 1) จดว่า guest ตัวไหนกำลังรัน
{ qm list  | awk '$3=="running"{print "qm",  $1}'
  pct list | awk '$2=="running"{print "pct", $1}'; } > /root/running-before-upgrade.txt

# 2) พื้นที่ไม่พอ = หยุด ไม่อัปเกรด (กัน kernel ลงไม่ครบ)
root_kb=$(df -k --output=avail /     | tail -1)
boot_kb=$(df -k --output=avail /boot | tail -1)
[ "$root_kb" -gt $((2 * 1024 * 1024)) ] || fail "/ เหลือไม่ถึง 2 GB"
[ "$boot_kb" -gt $((200 * 1024)) ]      || fail "/boot เหลือไม่ถึง 200 MB"

# 3) หยุด guest ทุกตัว
for id in $(qm list | awk '$3=="running"{print $1}'); do
  echo "qm stop $id"
  qm stop "$id" --timeout 90 || qm stop "$id" --skiplock 1
done
for id in $(pct list | awk '$2=="running"{print $1}'); do
  echo "pct stop $id"; pct stop "$id"
done

# 4) โชว์รายการก่อน  5) dist-upgrade เก็บ config เดิม
export DEBIAN_FRONTEND=noninteractive
apt-get update || fail "apt update"
apt list --upgradable 2>/dev/null
apt-get -y -o Dpkg::Options::=--force-confold dist-upgrade || fail "dist-upgrade"

# 6) ต้อง reboot ไหม แล้วเก็บกวาด
newest=$(ls -1 /boot/vmlinuz-* | sort -V | tail -1 | sed 's|/boot/vmlinuz-||')
[ "$(uname -r)" != "$newest" ] && echo "REBOOT-NEEDED running=$(uname -r) newest=$newest"
apt-get -y autoremove
echo "DONE-OK $(date +%T)" | tee "$MARK"
I deliberately included three things. First, I used dist-upgrade rather than plain upgrade, because Proxmox package dependencies keep changing between updates. A normal upgrade holds back packages that require additional new packages to be installed, leaving a mix of old and new components. Second, --force-confold always keeps the existing config file when a package supplies a new version, so nobody has to answer prompts halfway through the script. Third, I checked disk space first. If /boot fills up during kernel installation, the result is an incompletely installed kernel, which is harder to fix than not upgrading at all.
The controller on the admin machine had just one job: watch the markers on all three machines. If any node reported DONE-FAIL, it would skip reboots for the whole set and retrieve the last 20 lines of that machine's log for inspection. It waited no more than 80 minutes for the upgrade and no more than 15 minutes for each machine to reboot.
Two machines finished in five minutes; the other was still running
All three started at 19:04. Node C finished at 19:08:39 after upgrading 221 packages. Node A finished at 19:09:44 after upgrading 252 packages. Node B still had no marker. The owner asked why it was slow when it was usually fast, which was a fair question: all three had started together and were upgrading from the same repository.
The first question to answer before doing anything else was whether it was slow or stuck. Those two cases call for opposite decisions. If it is slow, wait. If it is stuck, investigate and fix it. Killing a dpkg process that is merely slow is a way to turn a healthy machine into one with packages left halfway through installation.
Distinguishing slow progress from a hang: locale-gen with 509 entries
I checked three things in order: whether the processes were still there, whether any counters were advancing, and whether any files were growing.
# 1) process ยังอยู่ไหม และรันมานานแค่ไหน (วินาที)
ps -eo pid,etimes,cmd | grep -E 'apt-get|dpkg|locale-gen|localedef' | grep -v grep
#  ... 186 /bin/sh /usr/sbin/locale-gen

# 2) เปิด locale ไว้กี่รายการ และคอมไพล์ไปแล้วกี่รายการ
grep -cvE '^(#|$)' /etc/locale.gen       # 509   (อีกสองเครื่องได้ 1)
localedef --list-archive | wc -l          # 354 -> อีก 40 วินาทีได้ 405

# 3) ไฟล์ archive โตไหม
ls -l /usr/lib/locale/locale-archive      # 141 MB -> 161 MB
dpkg and apt-get were still there, and the process taking the time was locale-gen, which had been running for 186 seconds. The locales package's postinst recompiles every locale enabled in /etc/locale.gen each time the package is updated. Node B had 509 entries enabled, while A and C each had 1. Work that the other two machines did once, this machine had to do 509 times.
The counter advanced from 354 to 405 in 40 seconds, or 1.27 locales per second. The locale-archive file grew from 141 MB to 161 MB. All three signals agreed that it was working, not stuck. With a rate, I could also estimate the time remaining. At a count of 405, around 100 entries remained, meaning less than two minutes. The earlier part had been slower because locales with large character tables, such as Chinese, were near the start of the alphabetical order. Once it passed that group, the rate increased. At completion, the archive contained 513 entries, and node B had upgraded 234 packages in total.
Wait; leave it alone
The dpkg process is still there, the count from localedef --list-archive increases on repeated checks, and the locale-archive file is growing. You can calculate the rate and estimate the completion time. Killing the process now leaves packages with configuration unfinished.
Investigate
The process is still there, but the counter does not move across several measurements, the file does not grow, and there is no I/O; or the process has disappeared but there is no marker. In the latter case, read the end of the log and then continue with dpkg --configure -a.
I did not investigate when those 509 entries had been enabled, and as of writing I have not reduced the number. But before the next update, I will check /etc/locale.gen on every machine and leave only the locales actually in use. Otherwise, every time the locales package changes, this machine will spend the same time doing it again.
Reboot one machine at a time, keeping 2 of 3 up
As for whether I could reboot the two finished machines first, the answer was yes, but one at a time, never together.
A three-node cluster has 3 votes and needs at least 2 to be quorate. If A and C go down together, only B remains, with 1 of 3 votes. The cluster loses quorum, and the immediate result is that /etc/pve, the pmxcfs filesystem, becomes read-only. Normally this just prevents config changes temporarily. But that night B was upgrading. The postinst scripts of some Proxmox packages being configured on B needed to write to /etc/pve. If they could not write, the scripts would fail midway, leaving the machine with unfinished package installations while the other two were still booting.
The actual sequence was to reboot A first, leaving B and C with 2 of 3 votes. I waited until A returned and the cluster was quorate with all nodes present, which happened at 19:16:03, then rebooted C and waited for it to return. After that, I waited for B to report DONE-OK and rebooted B last. Each machine took around 30 seconds to a few minutes to boot back up.
# ฝั่งเครื่อง admin: reboot หนึ่งเครื่อง แล้วรอจนเครื่องนั้นกลับมาเห็นคลัสเตอร์ quorate
reboot_one() {
  ssh root@"$1" 'systemctl reboot'
  sleep 60
  for i in $(seq 1 84); do                       # 60 + 84 x 10 วินาที = ไม่เกิน 15 นาที
    ssh -o ConnectTimeout=5 root@"$1" 'pvecm status | grep -q "Quorate:.*Yes"' && return 0
    sleep 10
  done
  echo "[ERR] $1 ไม่กลับมา quorate ภายใน 15 นาที"; return 1
}

reboot_one node-a || exit 1                      # เหลือ B + C = 2/3
reboot_one node-c || exit 1                      # เหลือ A + B = 2/3

# node-b เป็นตัวสุดท้าย และต้องอัปเกรดจบก่อนเท่านั้น
until ssh root@node-b 'grep -q DONE-OK /root/pve-upgrade.marker 2>/dev/null'; do sleep 30; done
reboot_one node-b
A 3-node cluster with only 1 node left is not quorate, and /etc/pve becomes unwritable. If the remaining machine is running a Proxmox package's postinst, a failed write will cause dpkg to fail midway. Reboot one machine at a time, always wait for Quorate: Yes before the next, and always leave the machine whose upgrade is unfinished until last.
Post-boot checks
Once all three machines were back, I ran through the same checklist I use every time. I did not trust a successful ping alone.
pvecm status | grep -E 'Quorate|Total votes|Expected votes'      # Quorate: Yes, 3/3
pveversion                                                        # ตัวจัดการเป็นรุ่นย่อยล่าสุด
uname -r                                                          # kernel ตัวใหม่
systemctl is-active pve-cluster corosync pvedaemon pveproxy pvestatd pve-firewall
systemctl is-active tunnel-in.service; systemctl is-enabled tunnel-in.service
qm list; pct list                                                 # guest ที่ควรรัน กลับมาครบไหม
The manager and kernel were on the latest minor releases on all three machines. pvecm status showed Quorate: Yes with all 3 of 3 present. All 6 core services were active, and the inbound tunnel used for remote access from outside was active and enabled with its existing settings, with no need to reconfigure it (the unit name in the example is a placeholder; use your own service name).
- Record the state of running guests before anyone stops anything, rather than having the script record it at startup.
- Check that
/has more than 2 GB free and/bootmore than 200 MB. If there is not enough space, stop and do not upgrade. - Run the upgrade script detached on all nodes at once if needed, ending with a
DONE-OKorDONE-FAILmarker. - For any slow node, check processes, counters, and file sizes. Measure the rate before deciding whether it is slow or stuck.
- If even one machine reports
DONE-FAIL, do not reboot any of them. Read the log first. - Reboot one machine at a time, waiting for
Quorate: Yeseach time. Leave the machine whose upgrade is unfinished until last. - Check quorum, versions, core services, the tunnel, and the guest list against the record from the first step.
An empty guest list file: 0 byte
The final lesson came from the script's first step itself. When I opened /root/running-before-upgrade.txt to see which guests had been running before the upgrade, the file was 0 byte on all three machines, and there was not a single qm stop line in the logs.
The script was not wrong. The owner had manually stopped all VMs before the script started. By the time the script reached the step that recorded the list, nothing was running for it to record. It correctly recorded an empty list. The only guests that came back up automatically after reboot were those configured with onboot: 1. Containers set to onboot: 0 did not come back on their own; someone had to remember that they had been running.
# ดูว่า guest ตัวไหนจะกลับมาเองหลังบูต และตัวไหนต้องมีคนเปิด
grep -H '^onboot' /etc/pve/qemu-server/*.conf /etc/pve/lxc/*.conf 2>/dev/null
grep -L '^onboot: 1' /etc/pve/qemu-server/*.conf /etc/pve/lxc/*.conf 2>/dev/null
Recording the state in the script's first step assumes the script is the first thing to touch the system, which is not true when other people are involved. A 0 byte file and a missing file provide the same amount of information: none. Record the state when taking on the job, before the instruction to stop all VMs is carried out.
Nothing broke that night, but there were three points where it could have if I had acted one step too quickly: killing dpkg on a machine that was merely slow, rebooting two machines together because they had finished, and trusting the guest list recorded by the script without opening it. All three are addressed the same way: measure before deciding. Check the counters before killing a process, check the votes before rebooting, and check the file size before trusting it. If you have a three-node cluster, feel free to use this sequence and adjust the timeouts for your own machines. If I have left anything out or made a typo, I will come back and correct it later.
Want us to set this up?
Get help with server setup, configuration, migration, or troubleshooting. Save time for the work that matters.
Hit something like this? Stuck somewhere?
Come trade notes on the LinuxThai board
Comments 0
No comments yet — be the first